

2022 Databricks-Certified-Professional-Data-Scientist Premium Files Test pdf - Free Dumps Collection
Get ready to pass the Databricks-Certified-Professional-Data-Scientist Exam right now using our Databricks Certification Exam Package
Databricks Databricks-Certified-Professional-Data-Scientist Exam Syllabus Topics:
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION 31
In statistics, maximum-likelihood estimation (MLE) is a method of estimating the parameters of a statistical model. When applied to a data set and given a statistical model, maximum-likelihood estimation provides estimates for the model's parameters and the normalizing constant usually ignored in MLEs because
- A. The normalizing constant only has a small impact on the maximum likelihood
- B. The normalizing constant is often zero and can cause division by zero
- C. The normalizing constant is always very close to 1
- D. The normalizing constant doesn't impact the maximizing value
Answer: D
Explanation:
Explanation
(Change the explanation even it is correct)A normalizing constant is positive, and multiplying or dividing a series of values by a positive number does not affect which of them is the largest. Maximum likelihood estimation is concerned only with finding a maximum value, so normalizing constants can be ignored.
NEW QUESTION 32
Refer to the Exhibit.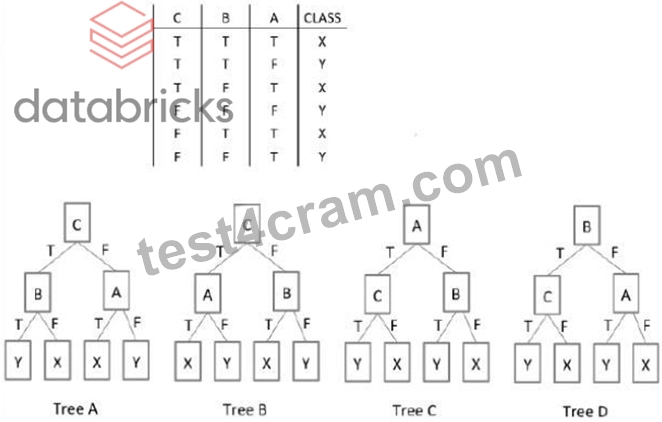
In the Exhibit, the table shows the values for the input Boolean attributes "A", "B", and "C". It also shows the values for the output attribute "class". Which decision tree is valid for the data?
- A. Tree A
- B. Tree B
- C. Tree C
- D. Tree D
Answer: B
NEW QUESTION 33
Suppose that the probability that a pedestrian will be tul by a car while crossing the toad at a pedestrian crossing without paying attention to the traffic light is lo be computed. Let H be a discrete random variable taking one value from (Hit. Not Hit). Let L be a discrete random variable taking one value from (Red. Yellow.
Green).
Realistically, H will be dependent on L That is, P(H = Hit) and P(H = Not Hit) will take different values depending on whether L is red, yellow or green. A person is. for example, far more likely to be hit by a car when trying to cross while Hie lights for cross traffic are green than if they are red In other words, for any given possible pair of values for Hand L. one must consider the joint probability distribution of H and L to find the probability* of that pair of events occurring together if Hie pedestrian ignores the state of the light Here is a table showing the conditional probabilities of being bit. defending on ibe stale of the lights (Note that the columns in this table must add up to 1 because the probability of being hit oi not hit is 1 regardless of the stale of the light.)
- A. marginal probability that P(H=Not Hit) is the sum of the H= Hit row
- B. The marginal probability P(H=Hit) is the sum along the H=Hit row of this joint distribution table, as this is the probability of being hit when the lights are red OR yellow OR green.
- C. marginal probability that P(H=Not Hit) is the sum of the H=Not Hit row
Answer: B,C
Explanation:
Explanation
The marginal probability P(H=Hit) is the sum along the H=Hit row of this joint distribution table, as this is the probability of being hit when the lights are red OR yellow OR green. Similarly, the marginal probability that P(H=Not Hit) is the sum of the H=Not Hit row
NEW QUESTION 34
Scenario: Suppose that Bob can decide to go to work by one of three modes of transportation, car, bus, or commuter train. Because of high traffic, if he decides to go by car. there is a 50% chance he will be late. If he goes by bus, which has special reserved lanes but is sometimes overcrowded, the probability of being late is only 20%. The commuter train is almost never late, with a probability of only 1 %, but is more expensive than the bus.
Suppose that Bob is late one day, and his boss wishes to estimate the probability that he drove to work that day by car. Since he does not know Which mode of transportation Bob usually uses, he gives a prior probability of
1 3 to each of the three possibilities. Which of the following method the boss will use to estimate of the probability that Bob drove to work?
- A. Naive Bayes
- B. None of the above
- C. Random decision forests
- D. Linear regression
Answer: A
Explanation:
Explanation
Bayes' theorem (also known as Bayes' rule) is a useful tool for calculating conditional probabilities.
NEW QUESTION 35
Question-34. Stories appear in the front page of Digg as they are "voted up" (rated positively) by the community. As the community becomes larger and more diverse, the promoted stories can better reflect the average interest of the community members. Which of the following technique is used to make such recommendation engine?
- A. Collaborative filtering
- B. Naive Bayes classifier
- C. Content-based filtering
- D. Logistic Regression
Answer: A
Explanation:
Explanation
One scenario of collaborative filtering application is to recommend interesting or popular information as judged by the community. As a typical example, stories appear in the front page of Digg as they are "voted up" (rated positively) by the community. As the community becomes larger and more diverse, the promoted stories can better reflect the average interest of the community members.
NEW QUESTION 36
A problem statement is given as below
Hospital records show that of patients suffering from a certain disease, 75% die of it. What is the probability that of 6 randomly selected patients, 4 will recover?
Which of the following model will you use to solve it.
- A. Normal
- B. Poisson
- C. Any of the above
- D. Binomial
Answer: D
NEW QUESTION 37
Which of the following technique can be used to the design of recommender systems?
- A. Collaborative filtering
- B. 2 and 3
- C. Naive Bayes classifier
- D. Power iteration
- E. 1 and 3
Answer: A
Explanation:
Explanation
One approach to the design of recommender systems that has seen wide use is collaborative filtering.
Collaborative filtering methods are based on collecting and analyzing a large amount of information on users' behaviors, activities or preferences and predicting what users will like based on their similarity to other users.
A key advantage of the collaborative filtering approach is that it does not rely on machine analyzable content and therefore it is capable of accurately recommending complex items such as movies without requiring an
"understanding" of the item itself. Many algorithms have been used in measuring user similarity or item similarity in recommender systems. For example the k-nearest neighbor (k-NN) approach and the Pearson Correlation
NEW QUESTION 38
The method based on principal component analysis (PCA) evaluates the features according to
- A. None of the above
- B. The projection of the smallest eigenvector of the correlation matrix on the initial dimensions
- C. According to the magnitude of the components of the discriminate vector
- D. The projection of the largest eigenvector of the correlation matrix on the initial dimensions
Answer: D
Explanation:
Explanation
Feature Selection:
The method based on principal component analysis (PCA) evaluates the features according to the projection of the largest eigenvector of the correlation matrix on the initial dimensions, the method based on Fisher's linear discriminate analysis evaluates. Them according to the magnitude of the components of the discriminate vector.
NEW QUESTION 39
Which of the following skills a data scientists required?
- A. He should possess database administrative skills.
- B. He should be creative
- C. Should be very good at mathematics and statistic
- D. Should possess good programming skills
- E. Web designing to represent best visuals of its results from algorithm.
Answer: B,C,D
Explanation:
Explanation
Yes a data scientists should have combination of skills like to solve the complex problem he should be creative as well as able to find new solutions and use of existing data. And solve the problem skills required are programming as currently we see SAS, R: Python, Spark, Java and SPSS even day by day new technologies are coming.
To apply various existing and new algorithm using Machine Learning, or Al it require good mathematics and statistics skills (Where the programmer feels, weaknesses). Another skill required is using visualization techniques like Qlik, Tableau etc
NEW QUESTION 40
If E1 and E2 are two events, how do you represent the conditional probability given that E2 occurs given that E1 has occurred?
- A. P(E2)/P(E1)
- B. P(E1)/P(E2)
- C. P(E2)/(P(E1+E2)
- D. P(E1+E2)/P(E1)
Answer: A
NEW QUESTION 41
Question-13. Which of the following is not the Classification algorithm?
- A. Neural Network
- B. Support Vector Machine
- C. None of the above
- D. Hidden Markov Models
- E. Logistic Regression
Answer: C
Explanation:
Explanation
Logistic regression
Logistic regression is a model used for prediction of the probability of occurrence of an event. It makes use of several predictor variables that may be either numerical or categories.
Support Vector Machines
As with naive Bayes, Support Vector Machines (or SVMs) can be used to solve the task of assigning objects to classes. But the way this task is solved is completely different to the setting in naive Bayes.
Neural Network
Neural Networks are a means for classifying multidimensional objects.
Hidden Markov Models
Hidden Markov Models are used in multiple areas of machine learning, such as speech recognition, handwritten letter recognition, or natural language processing.
NEW QUESTION 42
What are the advantages of the mutual information over the Pearson correlation for text classification problems?
- A. The mutual information doesn't assume that the variables are normally distributed.
- B. The mutual information is easier to parallelize.
- C. The mutual information can signal non-linear relationships between the dependent and independent variables.
- D. The mutual information has a meaningful test for statistical significance.
Answer: B
Explanation:
Explanation
A linear scaling of the input variables (that may be caused by a change of units for the measurements) is sufficient to modify the PCA results. Feature selection methods that are sufficient for simple distributions of the patterns belonging to different classes can fail in classification tasks with complex decision boundaries. In addition, methods based on a linear dependence (like the correlation) cannot take care of arbitrary relations between the pattern coordinates and the different classes. On the contrary, the mutual information can measure arbitrary relations between variables and it does not depend on transformations acting on the different variables.
This item concerns itself with feature selection for a text classification problem and references mutual information criteria. Mutual information is a bit more sophisticated than just selecting based on the simple correlation of two numbers because it can detect non-linear relationships that will not be identified by the correlation. Whenever possible: mutual information is a better feature selection technique than correlation.
Mutual information is a quantification of the dependency between random variables. It is sometimes contrasted with linear correlation since mutual information captures nonlinear dependence.
Correlation analysis provides a quantitative means of measuring the strength of a linear relationship between two vectors of data. Mutual information is essentially the measure of how much "knowledge" one can gain of a certain variable by knowing the value of another variable.
NEW QUESTION 43
You are working with the Clustering solution of the customer datasets. There are almost 40 variables are available for each customer and almost 1.00,0000 customer's data is available. You want to reduce the number of variables for clustering, what would you do?
- A. You can combine several variables in one variable
- B. You will randomly reduce the number of variables
- C. You cannot discard any variable for creating clusters.
- D. You will find the correlation among the variables and from the highly co-related variables, you will be considering only one or two variables from it.
- E. You will find the correlation among the variables and from their variables are not co-related will be discarded.
Answer: A,D
Explanation:
Explanation
When you are applying clustering technique and you find that there are quite a huge number of variables are available. Then it is better the find the co-relation among the variables and consider only one or two variables from the highly co-related variables. Because highly co-related variable will have the same effect, while creating the cluster. We can use scatter plot matrix among the variables to find the co-relation.
You can also combine several variables into a single variable. For example if you have two values in the dataset like Asset and Debt than by combining these two values like Debt to Asset ratio and use it while creating the cluster.
NEW QUESTION 44
You have modeled the datasets with 5 independent variables called A,B,C,D and E having relationships which is not dependent each other, and also the variable A,B and C are continuous and variable D and E are discrete (mixed mode).
Now you have to compute the expected value of the variable let say A, then which of the following computation you will prefer
- A. Transformation
- B. Integration
- C. Differentiation
- D. Generalization
Answer: B
Explanation:
Explanation
Text Description automatically generated
Text Description automatically generated
Text Description automatically generated
NEW QUESTION 45
Which of the following statement true with regards to Linear Regression Model?
- A. Ordinary Least Square is a sum of the individual distance between each point and the fitted line of regression model.
- B. Ordinary Least Square can be used to estimates the parameters in linear model
- C. Ordinary Least Square is a sum of the squared individual distance between each point and the fitted line of regression model.
- D. In Linear model, it tries to find multiple lines which can approximate the relationship between the outcome and input variables.
Answer: B,C
Explanation:
Explanation
Linear regression model are represented using the below equation
Where B(0) is intercept and B(1) is a slope. As B(0) and B(1) changes then fitted line also shifts accordingly on the plot. The purpose of the Ordinary Least Square method is to estimates these parameters B(0) and B(1).
And similarly it is a sum of squared distance between the observed point and the fitted line. Ordinary least squares (OLS) regression minimizes the sum of the squared residuals. A model fits the data well if the differences between the observed values and the model's predicted values are small and unbiased.
NEW QUESTION 46
What are the key outcomes of the successful analytical projects?
- A. Code of the model
- B. Presentations for the Analysts
- C. Technical specifications
- D. Presentation for Project Sponsors
Answer: A,B,C,D
Explanation:
Explanation
When your analytical project successfully completed they come up with the following at the end of the projects. Presentations- You will be having presentations like for the all the stakeholders, generally these presentation will help seniors executives to make better decisions. Similarly you would be creating presentations for the other teams like analysts various visuals you would be creating like ROC Curves, Heat Maps, and Bar Charts etc.
Whatever tools you have used like SAS, R, or Python then accordingly code was developed and you will get that code as one of the outcome. Also you would have created a technical specifications for implementing the codes.
NEW QUESTION 47
In which phase of the data analytics lifecycle do Data Scientists spend the most time in a project?
- A. Discovery
- B. Model Building
- C. Communicate Results
- D. Data Preparation
Answer: D
NEW QUESTION 48
......
Master 2022 Latest The Questions Databricks Certification and Pass Databricks-Certified-Professional-Data-Scientist Real Exam!: https://www.test4cram.com/Databricks-Certified-Professional-Data-Scientist_real-exam-dumps.html